Profile
About me
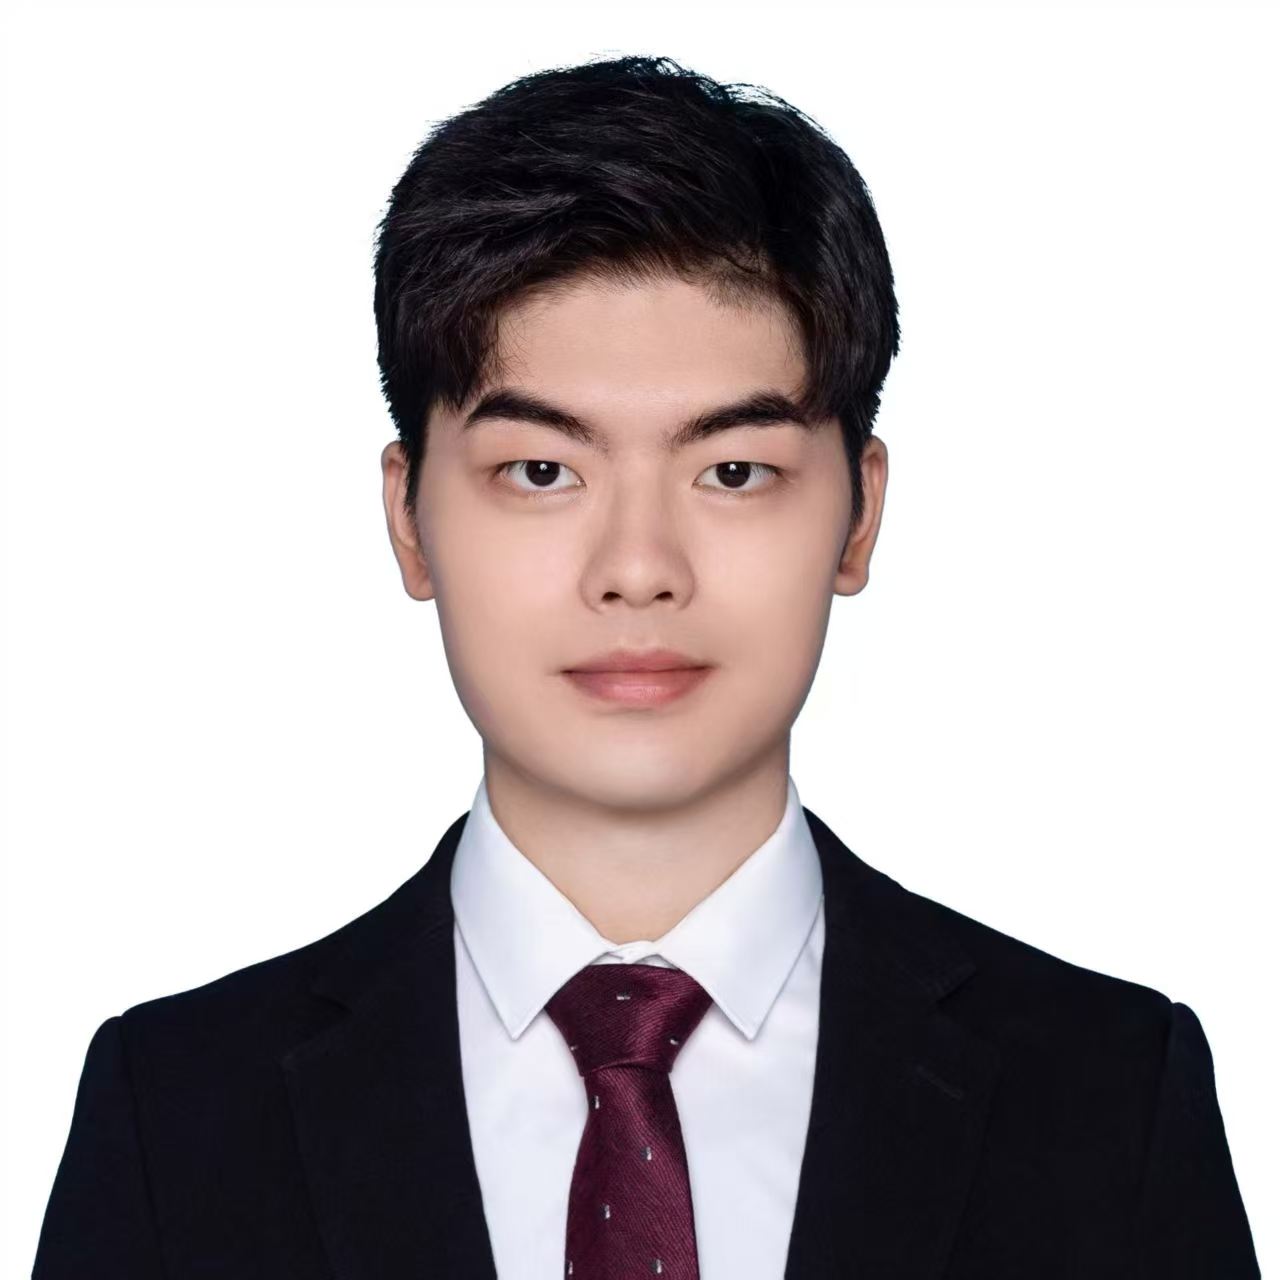
I am a master's student in Software Engineering at Peking University. My research spans LLM post-training, reinforcement learning for agents, LLM evaluation and reward modeling, diffusion language models, and multimodal or embodied intelligence. I firmly believe that research should start with real business needs and return to serve them. I have two first-author papers and one co-authored paper accepted at conferences rated Category A by Tsinghua University.
My research aims to move language models from generating answers to taking reliable action: enabling autoregressive and diffusion models to learn from verifiable feedback, improve through tools, vision, and real-world interaction, and translate capability gains into measurable value.
At Tencent CSIG, WorkBuddy Team × Youtu Lab, I research Code Agent post-training, with a focus on evaluation improvements for WorkBuddy Bench, web-agent evaluation, training data, and reinforcement learning, connecting real user needs, capability diagnosis, and model training to enable continuous evolution through an iterative feedback loop.
Research directions
From failure modes to training, evaluation, and systems.
Foundation Models & Post-training
Training objectives and inference methods that improve model capability without hiding failure modes behind aggregate scores.
Agents & Reinforcement Learning
Credit assignment, tool use, and reward design for agents that must interact with environments rather than only generate text.
Evaluation & Reward Modeling
Robust LLM judges, long-form evaluation, uncertainty, and reward models whose scores reflect what users actually care about.
Multimodal, VLM & Embodied AI
Visual feedback and robot reward models that connect language-model reasoning with perception and action.